08
Nov
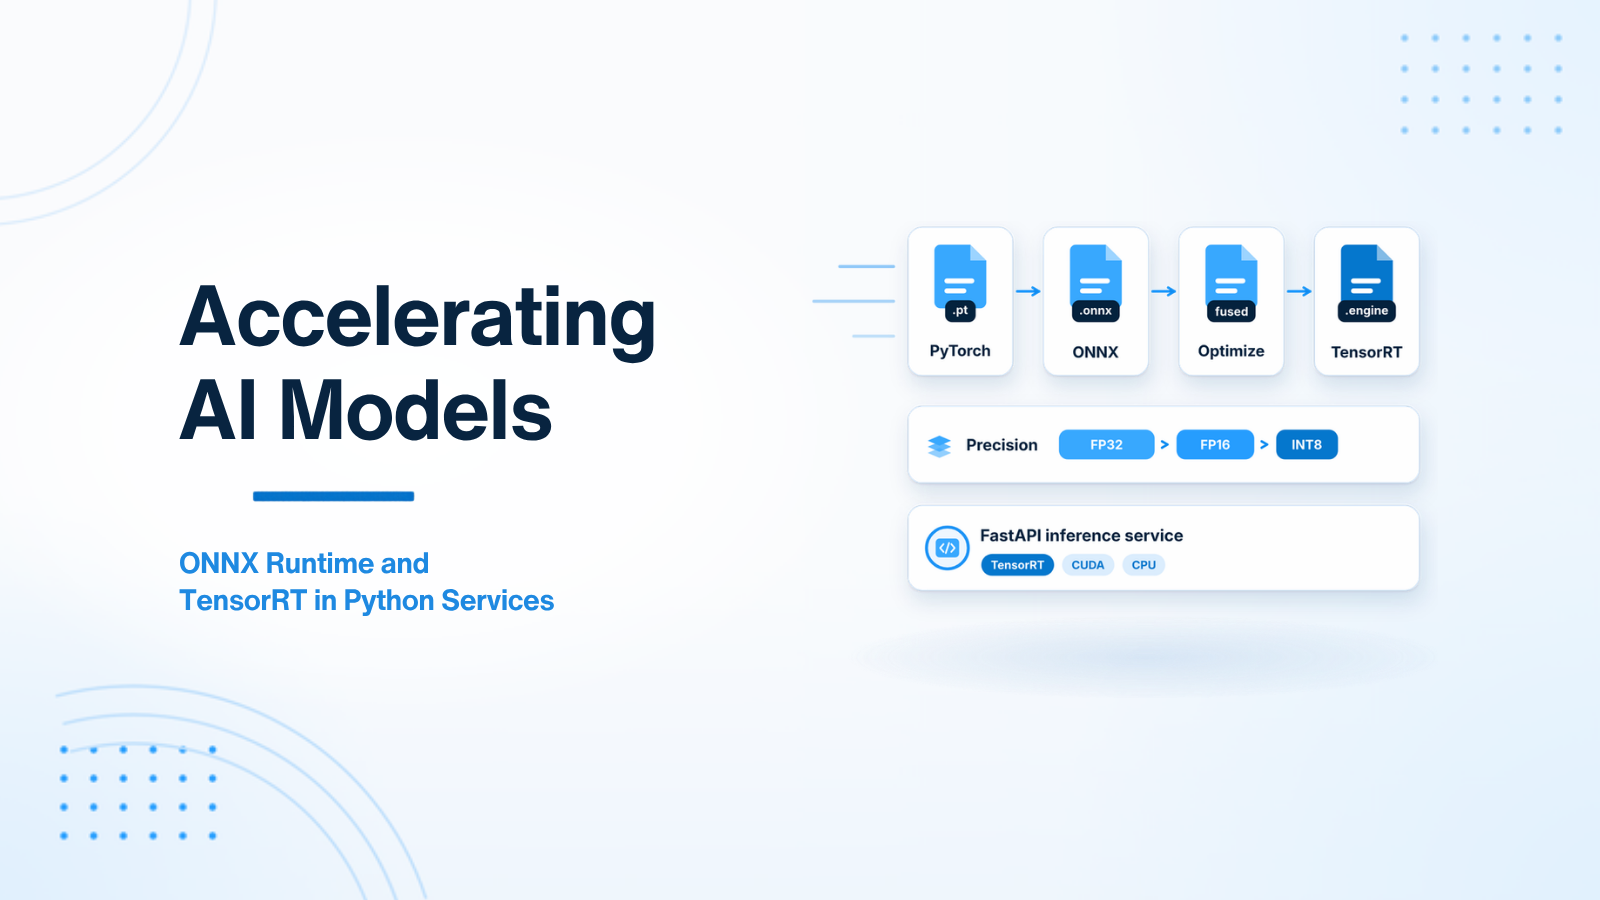
Accelerating AI Models with ONNX Runtime and TensorRT in Python Services
A practical, 1,500+ word engineering guide to accelerating AI model inference speed using ONNX Runtime and NVIDIA TensorRT in Python web services — covering model export, graph optimization, FP16/INT8 precision, and C++ engine execution.