Python AI Development: FastAPI, RAG, LLM APIs & Agents

Ship production Python AI services: FastAPI orchestration, retrieval-augmented generation, streaming chat backends, and agents with human review, wired next to Laravel or Node product systems.

Python AI backends that sit cleanly next to real products.

Python is the practical language for many RAG pipelines, LLM SDKs, and agent workflows. FastAPI turns that tooling into a service your product can call with auth, logging, and deploy habits.

I help teams ship Python AI development as a FastAPI backend: retrieval over company data, streaming chat endpoints, OpenAI and Claude orchestration, and agents with human review where needed.

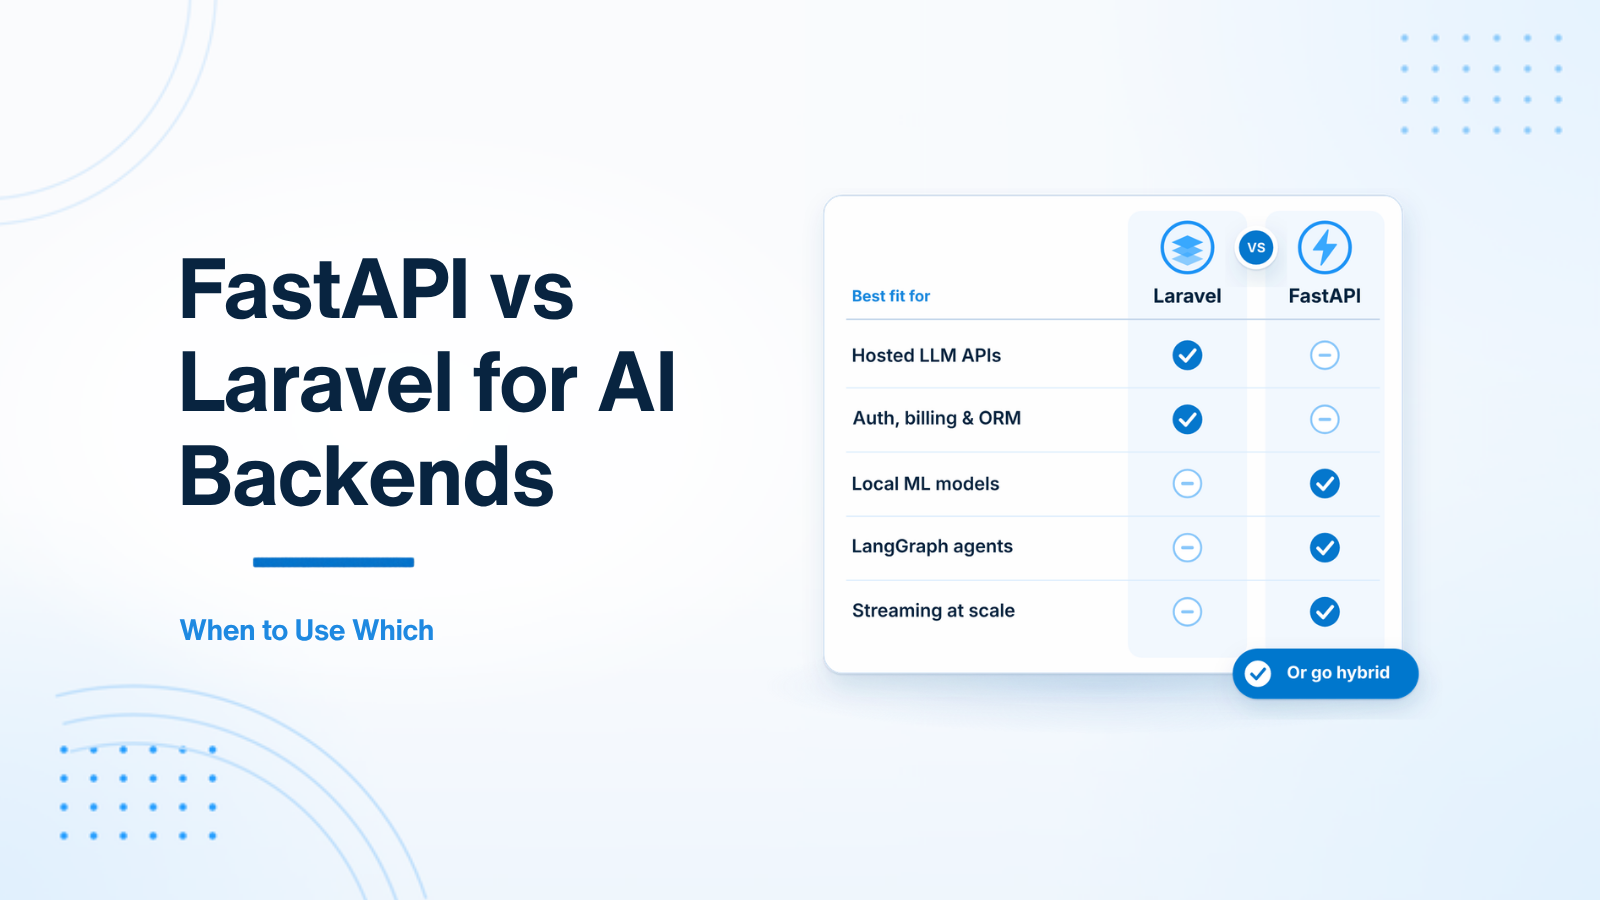
The signature pattern is hybrid: Laravel or Node keeps the product API, while FastAPI owns AI workers. That keeps billing and domain logic stable while you move fast on AI features.

If you want to hire for AI product delivery, use Hire AI Developer. If you need broader Python API capacity, use Hire Python Developer. This Python AI page bridges those two. The last-mile sidecar pattern also sits on the AI-first Forward Deployed Engineer page.

What this page covers

  • FastAPI AI backends
  • Python RAG pipelines
  • LLM APIs (OpenAI / Claude)
  • Agents with human review
  • Laravel + FastAPI hybrid architecture
  • Streaming, cost control, monitoring

Signature hybrid: Laravel + FastAPI AI

Keep product systems stable. Put AI workers where the Python ecosystem is strongest.

  1. 1Client / Admin UI (React or Laravel)
  2. 2Laravel / Node Product API (auth, billing, domain)
  3. 3FastAPI AI Service (RAG, LLM, agents, OCR)
  4. 4Postgres + pgvector + Redis + object storage

This is the same architecture pattern used on FastAPI Development and Hire AI Developer pages.

Python AI stack

RAG, LLM APIs, FastAPI, and hybrid architecture for production AI backends.

Python AI Development Python AI Developer FastAPI AI Backend Python RAG Pipeline LLM Application Development OpenAI API Python Claude API Python LangChain Python AI Agents Python Vector Search Python Laravel + FastAPI AI Streaming Chat Backend Hire Python AI Developer Ahmedabad Python AI

Who this is for

Clear fits for Python AI development so we start with the right service boundary.

Teams building RAG over company data

You need grounded answers over docs, tickets, or product knowledge with a Python retrieval pipeline.

Laravel / Node products adding AI

You want a FastAPI sidecar instead of stuffing every LLM call into the product monolith.

Startups validating AI agents

You need tool-using workflows with human review gates, streaming chat, and a path to production.

Python AI capabilities

FastAPI AI services, RAG, LLM APIs, agents, hybrid architecture, and production controls.

FastAPI AI Service Layer

A dedicated Python service for LLM calls, retrieval, and tool use, with clear contracts to your product API.

RAG Pipelines in Python

Chunking, embeddings, retrieval, and grounded generation over docs, tickets, or product knowledge.

LLM API Orchestration

OpenAI and Claude workflows with retries, streaming, token budgets, and structured outputs where useful.

Agents with Human Review

Tool-using agents for search, lookups, or ops actions, with approval gates when risk is high.

Hybrid Laravel + FastAPI Architecture

Keep auth, billing, and domain logic in Laravel or Node. Put AI workers in FastAPI where the ecosystem is strongest.

Vector Search & Storage

pgvector, Pinecone, or similar stores wired into retrieval flows with practical indexing and refresh habits.

Streaming Chat Backends

FastAPI streaming endpoints for chat UIs, with cancellation, logging, and safe fallbacks.

Cost, Privacy, Monitoring

Token awareness, safer data handling, and observability so Python AI features stay affordable and trustworthy.

Engagement models

Choose how we work based on roadmap urgency and ownership needs.

Python AI project

Best for a defined RAG module, LLM API service, or agent workflow with a clear done state.

AI MVP sprint

Best for validating a Python AI backend in weeks: architecture, core workflow, and a shippable first version.

Dedicated AI hire

Best when AI is on the roadmap for months. Start from Hire AI Developer for commercial engagement options.

Ahmedabad based, remote ready

Local presence for India clients, asynchronous delivery for global product teams.

  • Python AI developer Ahmedabad

    Based in Ahmedabad, Gujarat, with India-friendly collaboration and clear written updates.

  • Remote Python AI delivery

    Overlap hours for US, UK, and EU teams plus Slack, GitHub, and issue tracking for async speed.

  • Cost and privacy discipline

    Token budgets, safer data handling, and monitoring treated as product requirements.

Start the Python AI conversation

Use the contact form with category AI for product AI work, or Python when the need is primarily a FastAPI backend.

FastAPI sidecars in Forward Deployed work

A FastAPI AI sidecar next to the product API is a classic last-mile pattern. See AI-first Forward Deployed Engineer for the embed loop, or Hire Forward Deployed Engineer for named sprints.

Python AI development FAQs

Common questions about FastAPI AI backends, hybrid Laravel stacks, RAG, LangChain, and hiring paths.

Much of the LLM, embedding, and agent tooling is Python-first. A FastAPI sidecar lets you use that ecosystem while Laravel or Node keeps product systems stable.

Laravel (or Node) owns auth, billing, and domain APIs. FastAPI owns RAG, LLM orchestration, and AI workers. Both share Postgres, Redis, or object storage as needed.

Yes. Chunking, embeddings, retrieval, and grounded generation are a common FastAPI AI service deliverable, with clear APIs for the product UI.

LangChain or similar when orchestration helps. For simpler features, direct OpenAI or Claude SDKs inside FastAPI keep the stack lean.

Closely related. This page focuses on Python AI backends and FastAPI delivery. Hire AI Developer covers commercial AI hiring for RAG, chatbots, agents, and GenAI product features.

Yes. FastAPI streaming endpoints are a strong fit for chat experiences, with careful handling of timeouts and partial failures.

Model choice, retrieval limits, caching where safe, token budgets, and usage logging so spend stays visible.

Yes. Based in Ahmedabad, Gujarat, working with India and global clients on project, MVP sprint, or dedicated engagements.