
08
Nov
Building an OpenAI API Service with FastAPI
A practical guide to building an enterprise-grade OpenAI API microservice in FastAPI featuring rate limiting, fallback routing, and token cost logging.
Browse FastAPI articles on software engineering, AI, and product delivery.
Articles on architecture, APIs, Laravel, React/Next.js, cloud, databases, event-driven systems, AI, and mobile.
Articles on building production-ready applications with frontend, backend, database, and cloud architecture.
Browse Full-stack topicsGuides on API design, services, WebSocket, Node.js, Laravel backends, and integration patterns.
Browse API contentBest practices for Laravel applications, PHP architecture, Eloquent, Blade, and production maintenance.
Browse Laravel contentFrontend tutorials for React, Next.js, SEO-friendly rendering, and modern UI development.
Browse React contentCloud deployment, Docker, CI/CD, monitoring, and production infrastructure best practices.
Browse cloud contentDatabase architecture, optimization, caching, and storage strategies for scalable systems.
Browse database contentEvent-driven systems, streaming architecture, and asynchronous workflows for real-time products.
Browse event-driven contentRAG, agents, OpenAI/Claude integrations, GenAI features, and production AI patterns for SaaS products.
Browse AI contentLangChain, LangGraph, and framework comparisons for product engineers shipping LLM features.
Browse AI frameworksCross-platform mobile development, React Native, and app release planning for product teams.
Browse mobile content
A practical guide to building an enterprise-grade OpenAI API microservice in FastAPI featuring rate limiting, fallback routing, and token cost logging.
An honest comparison of Django and FastAPI when adding AI features: RAG, LLM APIs, admin workflows, and hybrid product architecture.
Learn how to write optimized, multi-stage Dockerfiles for Python and FastAPI applications with small image sizes, non-root security, and fast build caching.
A practical architecture for document intelligence in Python: OCR, field extraction with LLMs, confidence scores, and human review queues.
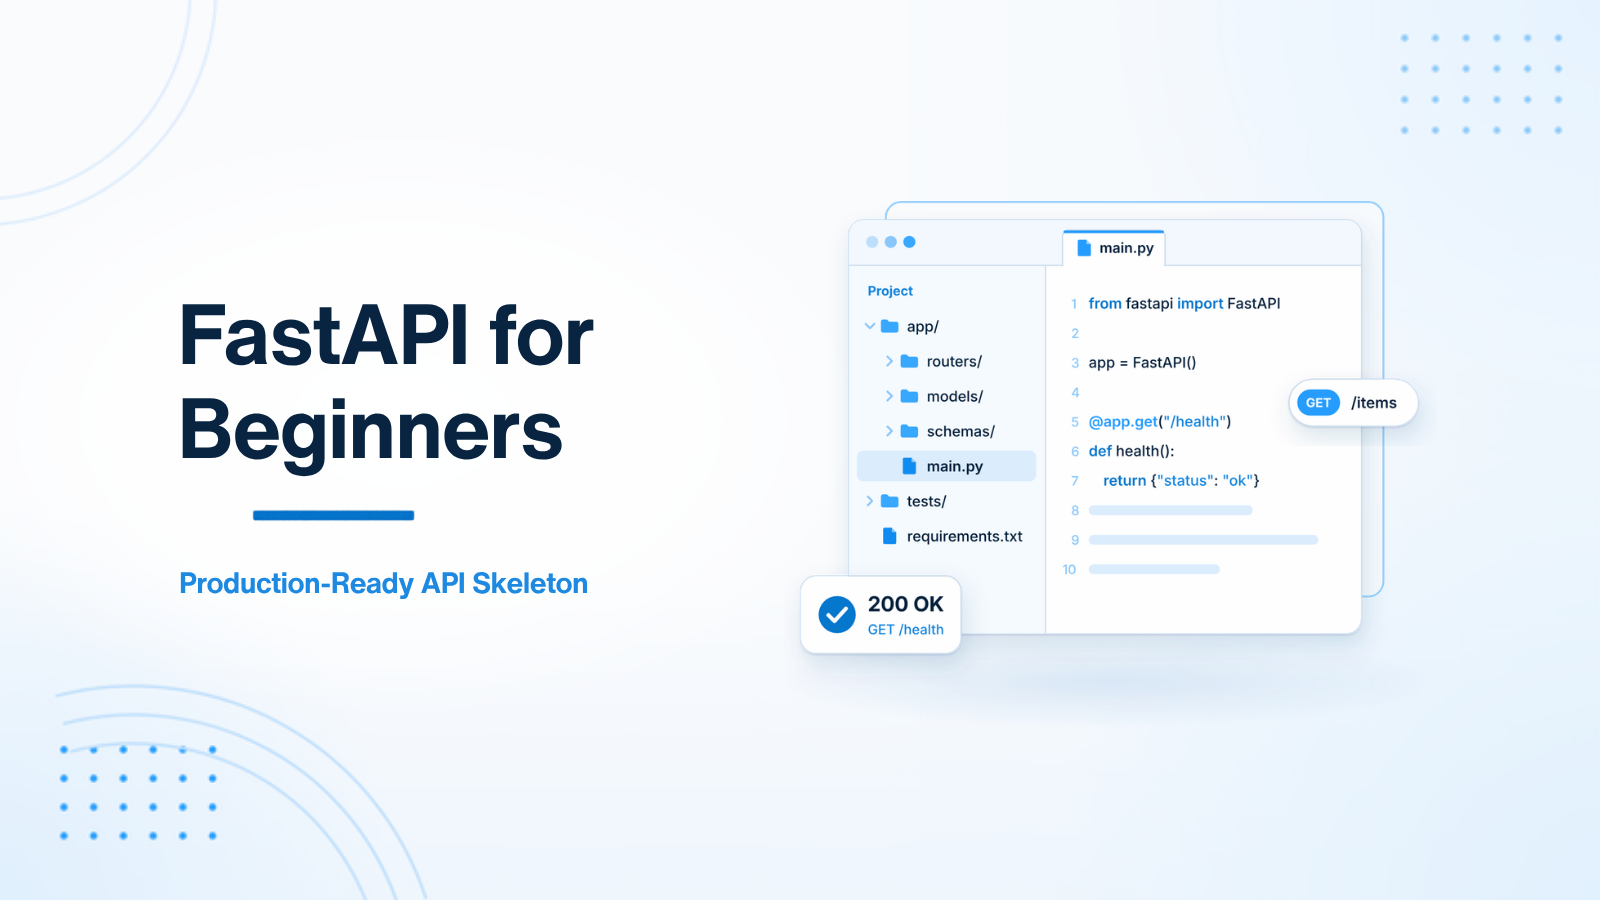
Step-by-step guide to building a modular, production-ready FastAPI project skeleton complete with routes, Pydantic schemas, dependency injection, and CORS.
Architect a robust production backend combining FastAPI for route handling, PostgreSQL for relational storage, and Redis for caching and rate limiting.
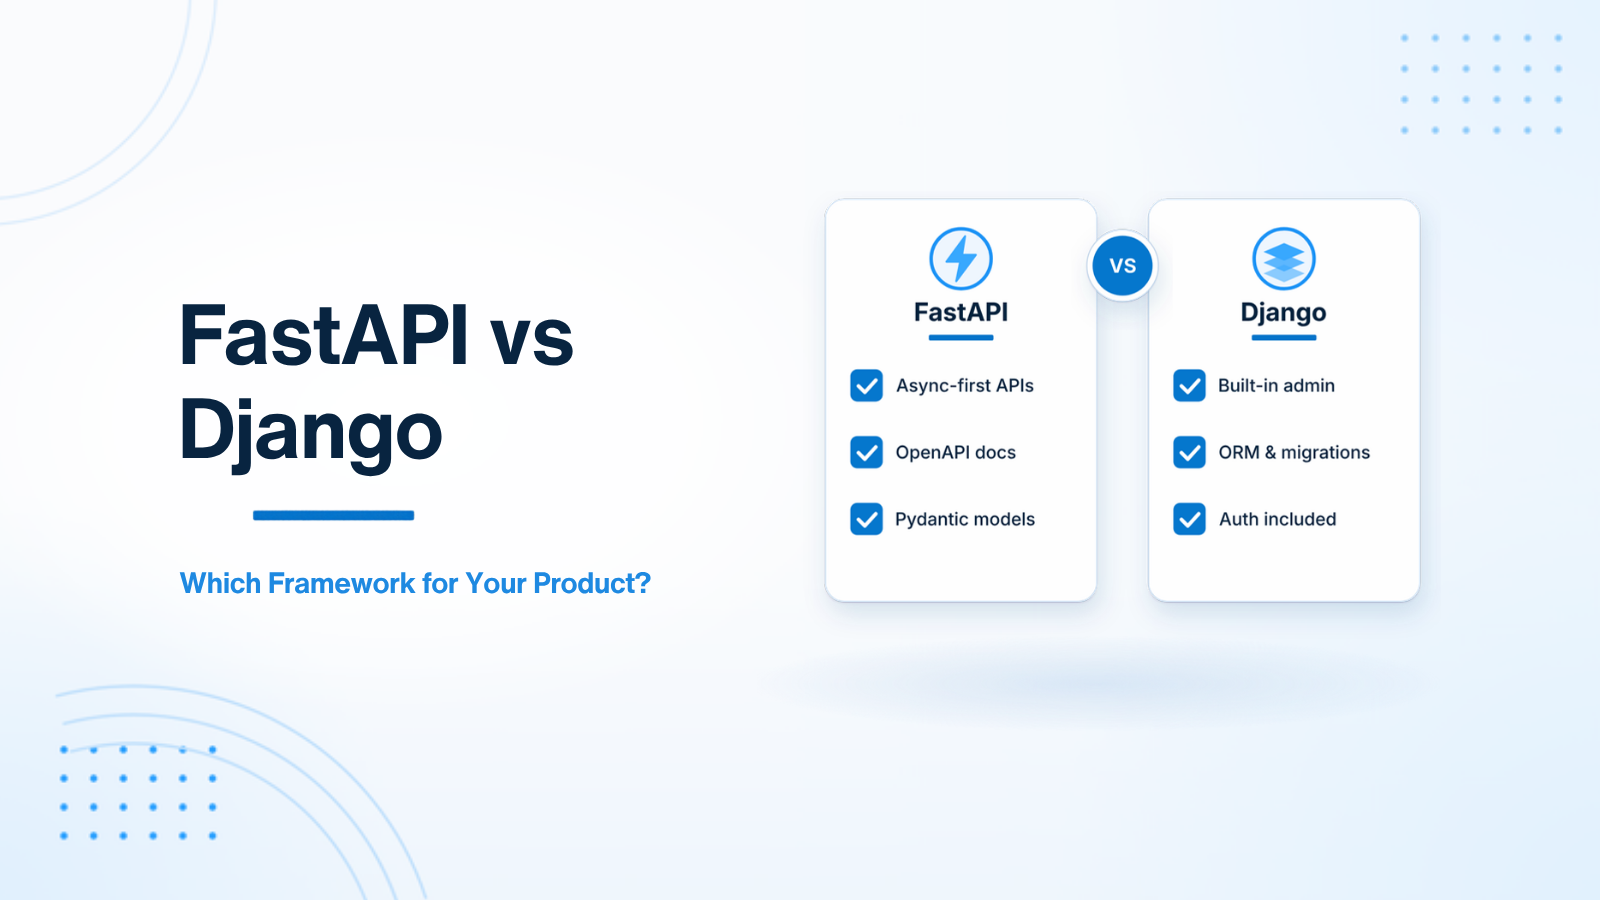
Compare FastAPI and Django side-by-side on performance, batteries-included tooling, admin interface, async support, and ecosystem fit.
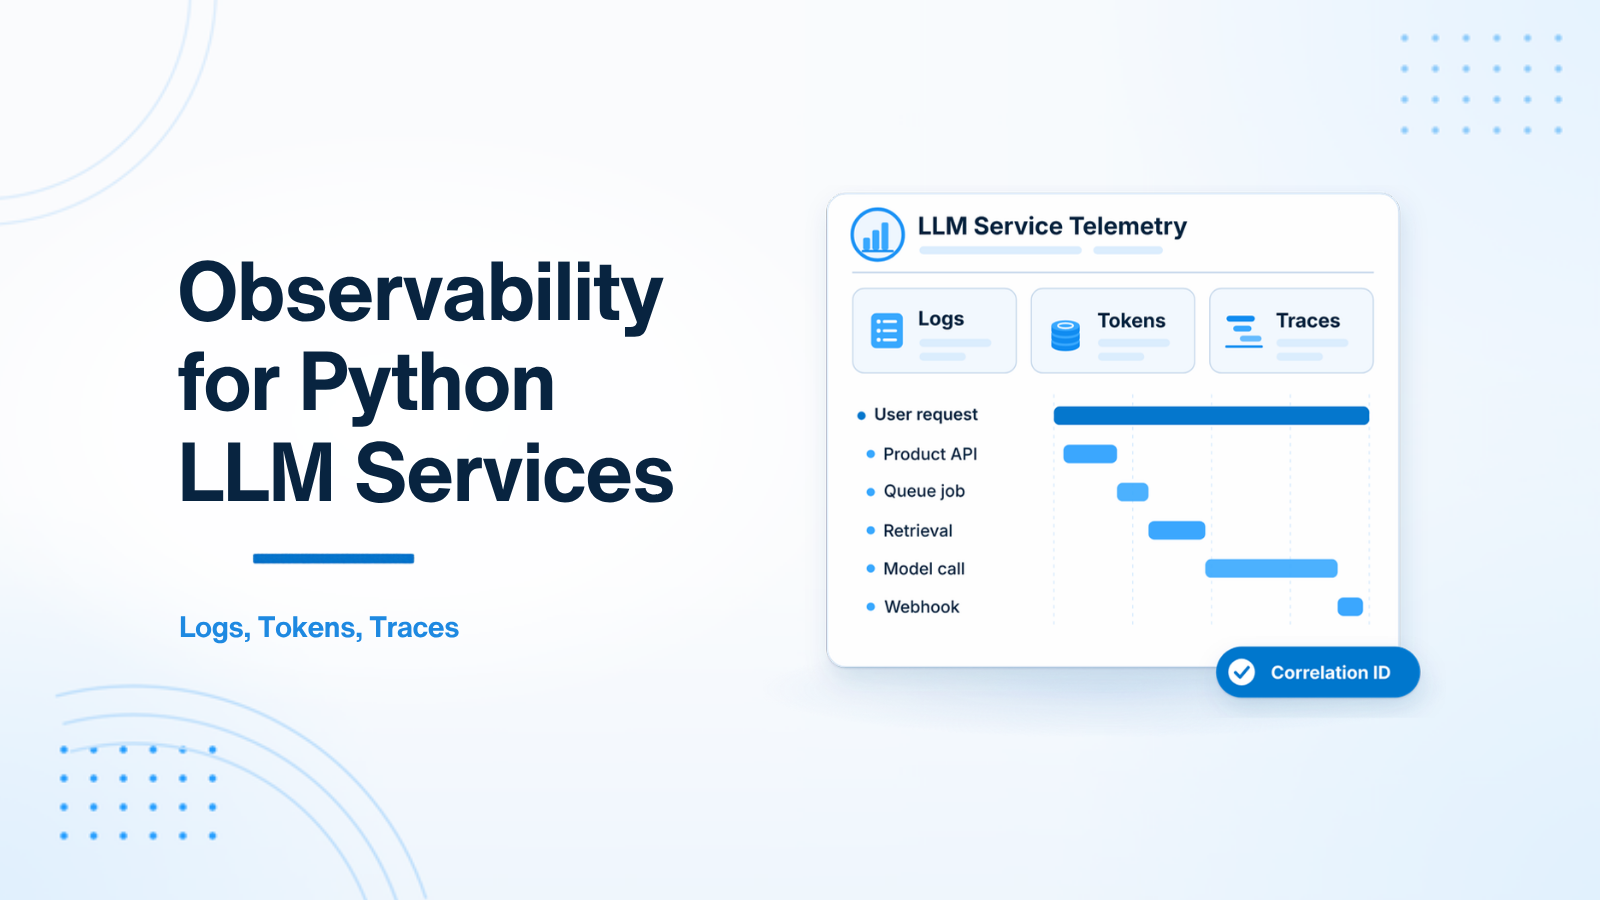
How to observe Python LLM services in production: structured logs, token cost tracking, traces, and quality signals beyond uptime checks.
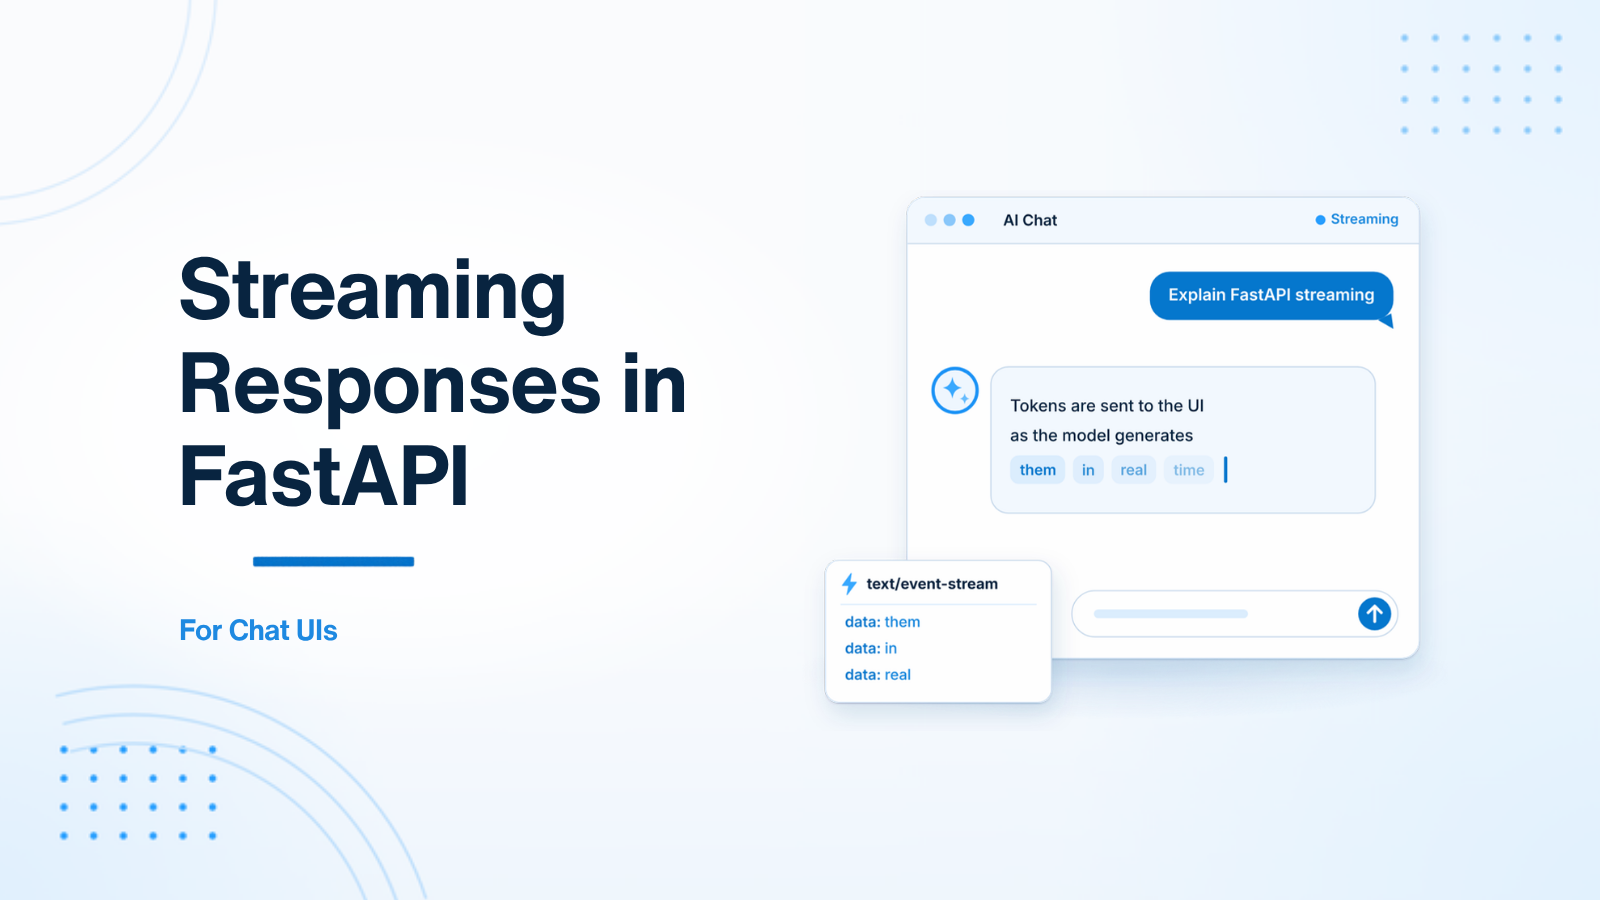
Build real-time streaming response endpoints in FastAPI using Server-Sent Events (SSE) and StreamingResponse for AI chat interfaces.
Learn how to use Python type hints and Pydantic v2 to build type-safe, self-documenting, and crash-resistant REST APIs.
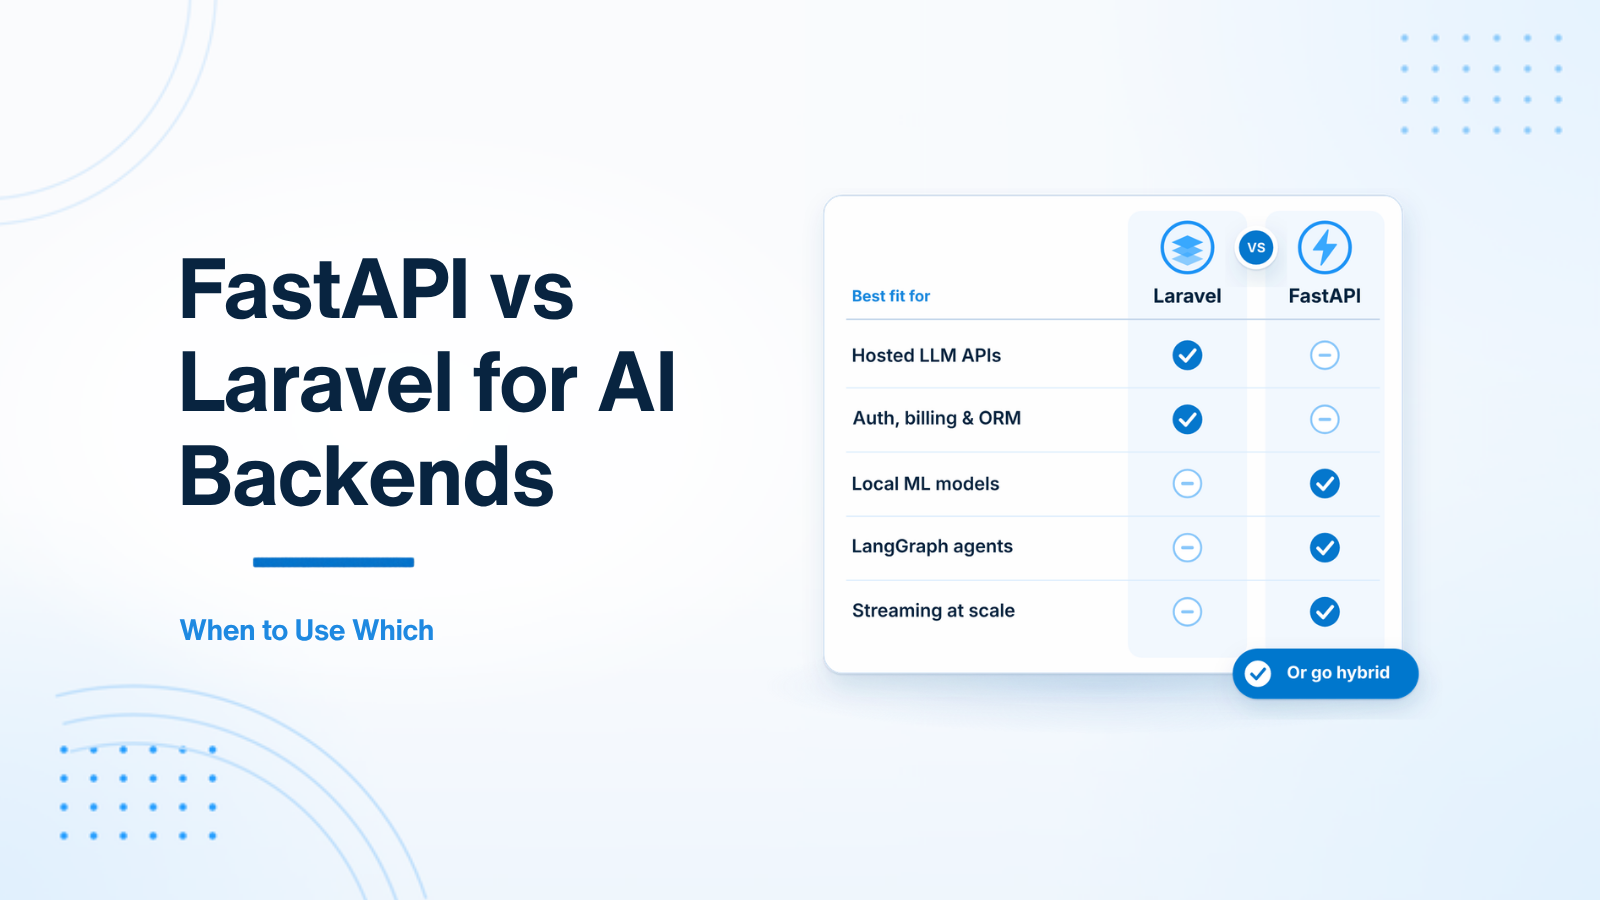
A comprehensive, 1,700+ word architectural decision guide comparing FastAPI and Laravel for AI backends — evaluating hosted API orchestration, local ML ecosystem access, database integration, async performance, and hybrid architectures.
A practical, 1,500+ word engineering guide to serving PyTorch and Hugging Face models inside FastAPI microservices — async request handling, lifespan context startup, batch processing, GPU concurrency, and Docker packaging.