An LLM service that is “up” can still be failing: answers drift, costs spike, latency climbs, and nobody can explain why. Observability for Python AI backends must cover more than HTTP 200s. You need logs, token economics, traces, and quality signals.
1. Structured logs with correlation IDs
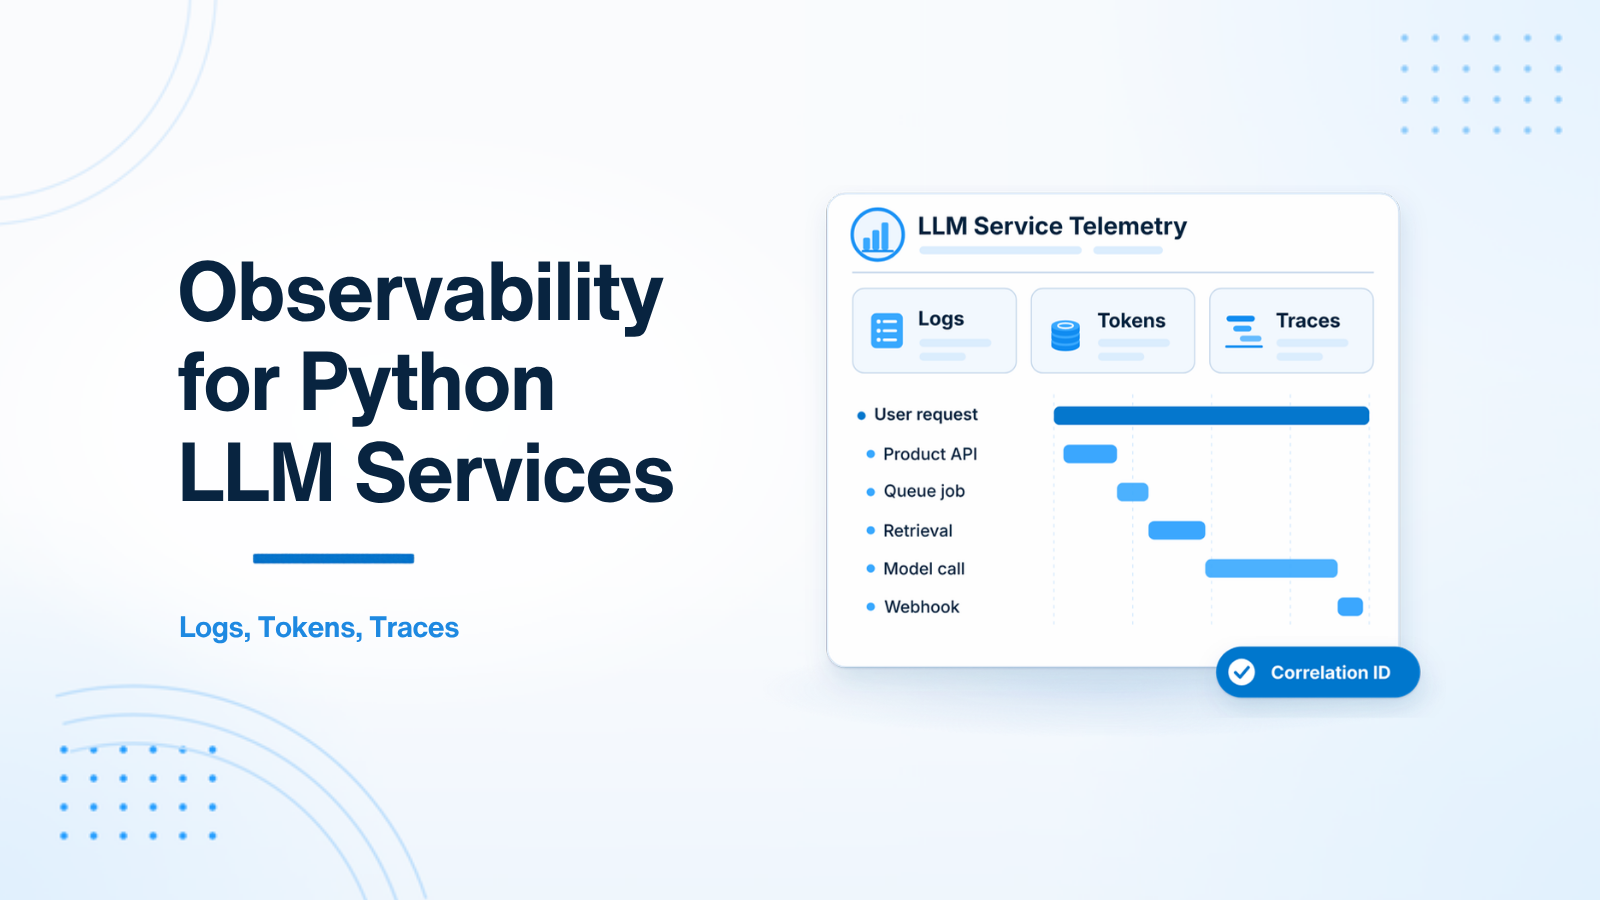
Every request should carry a correlation ID from the product API into the FastAPI AI service and workers. Log model name, prompt version, retrieval hit count, latency, and outcome class (ok, low_confidence, escalated, error). Prefer JSON logs your aggregator can query.
2. Token and cost metrics
Track input tokens, output tokens, and estimated cost per feature and per tenant. Alert on sudden spend spikes. Cache safe repeated prompts. Cap max tokens per route. Without this, a popular feature becomes a surprise invoice.
3. Traces across hybrid stacks
In Laravel + FastAPI hybrids, a user action may cross product API → queue → FastAPI → model provider → webhook. Trace that path. When a chat answer is wrong, you need to know whether retrieval, prompting, or the model call failed.
4. Quality signals, not only infra signals
- User thumbs up/down or edit distance on drafts
- Escalation rate to humans
- Citation missing rate for RAG
- Schema validation failure rate for structured outputs
These tell you if the AI is useful, not merely reachable.
5. Safe data in telemetry
Do not dump raw PII into logs. Redact or hash sensitive fields. Keep prompt/response archives under retention policy. Observability that violates privacy will get the feature shut down.
Practical FastAPI checklist
- Middleware for request IDs and timing
- Metrics endpoint or exporter for tokens and latency
- Per-route budgets and rate limits
- Dead-letter visibility for failed jobs
- Weekly review of top error classes and spend drivers
Summary
Production Python LLM services need operational telemetry: correlated logs, token economics, distributed traces, and quality feedback. Uptime alone is not enough.
Building an AI service that finance and ops can trust? See Python AI development or Hire AI Developer.

Prakash Tank
Full-Stack Architect & Tech Enthusiast. Passionate about building scalable applications and sharing knowledge with the community.